Your System is Fast—In the Lab
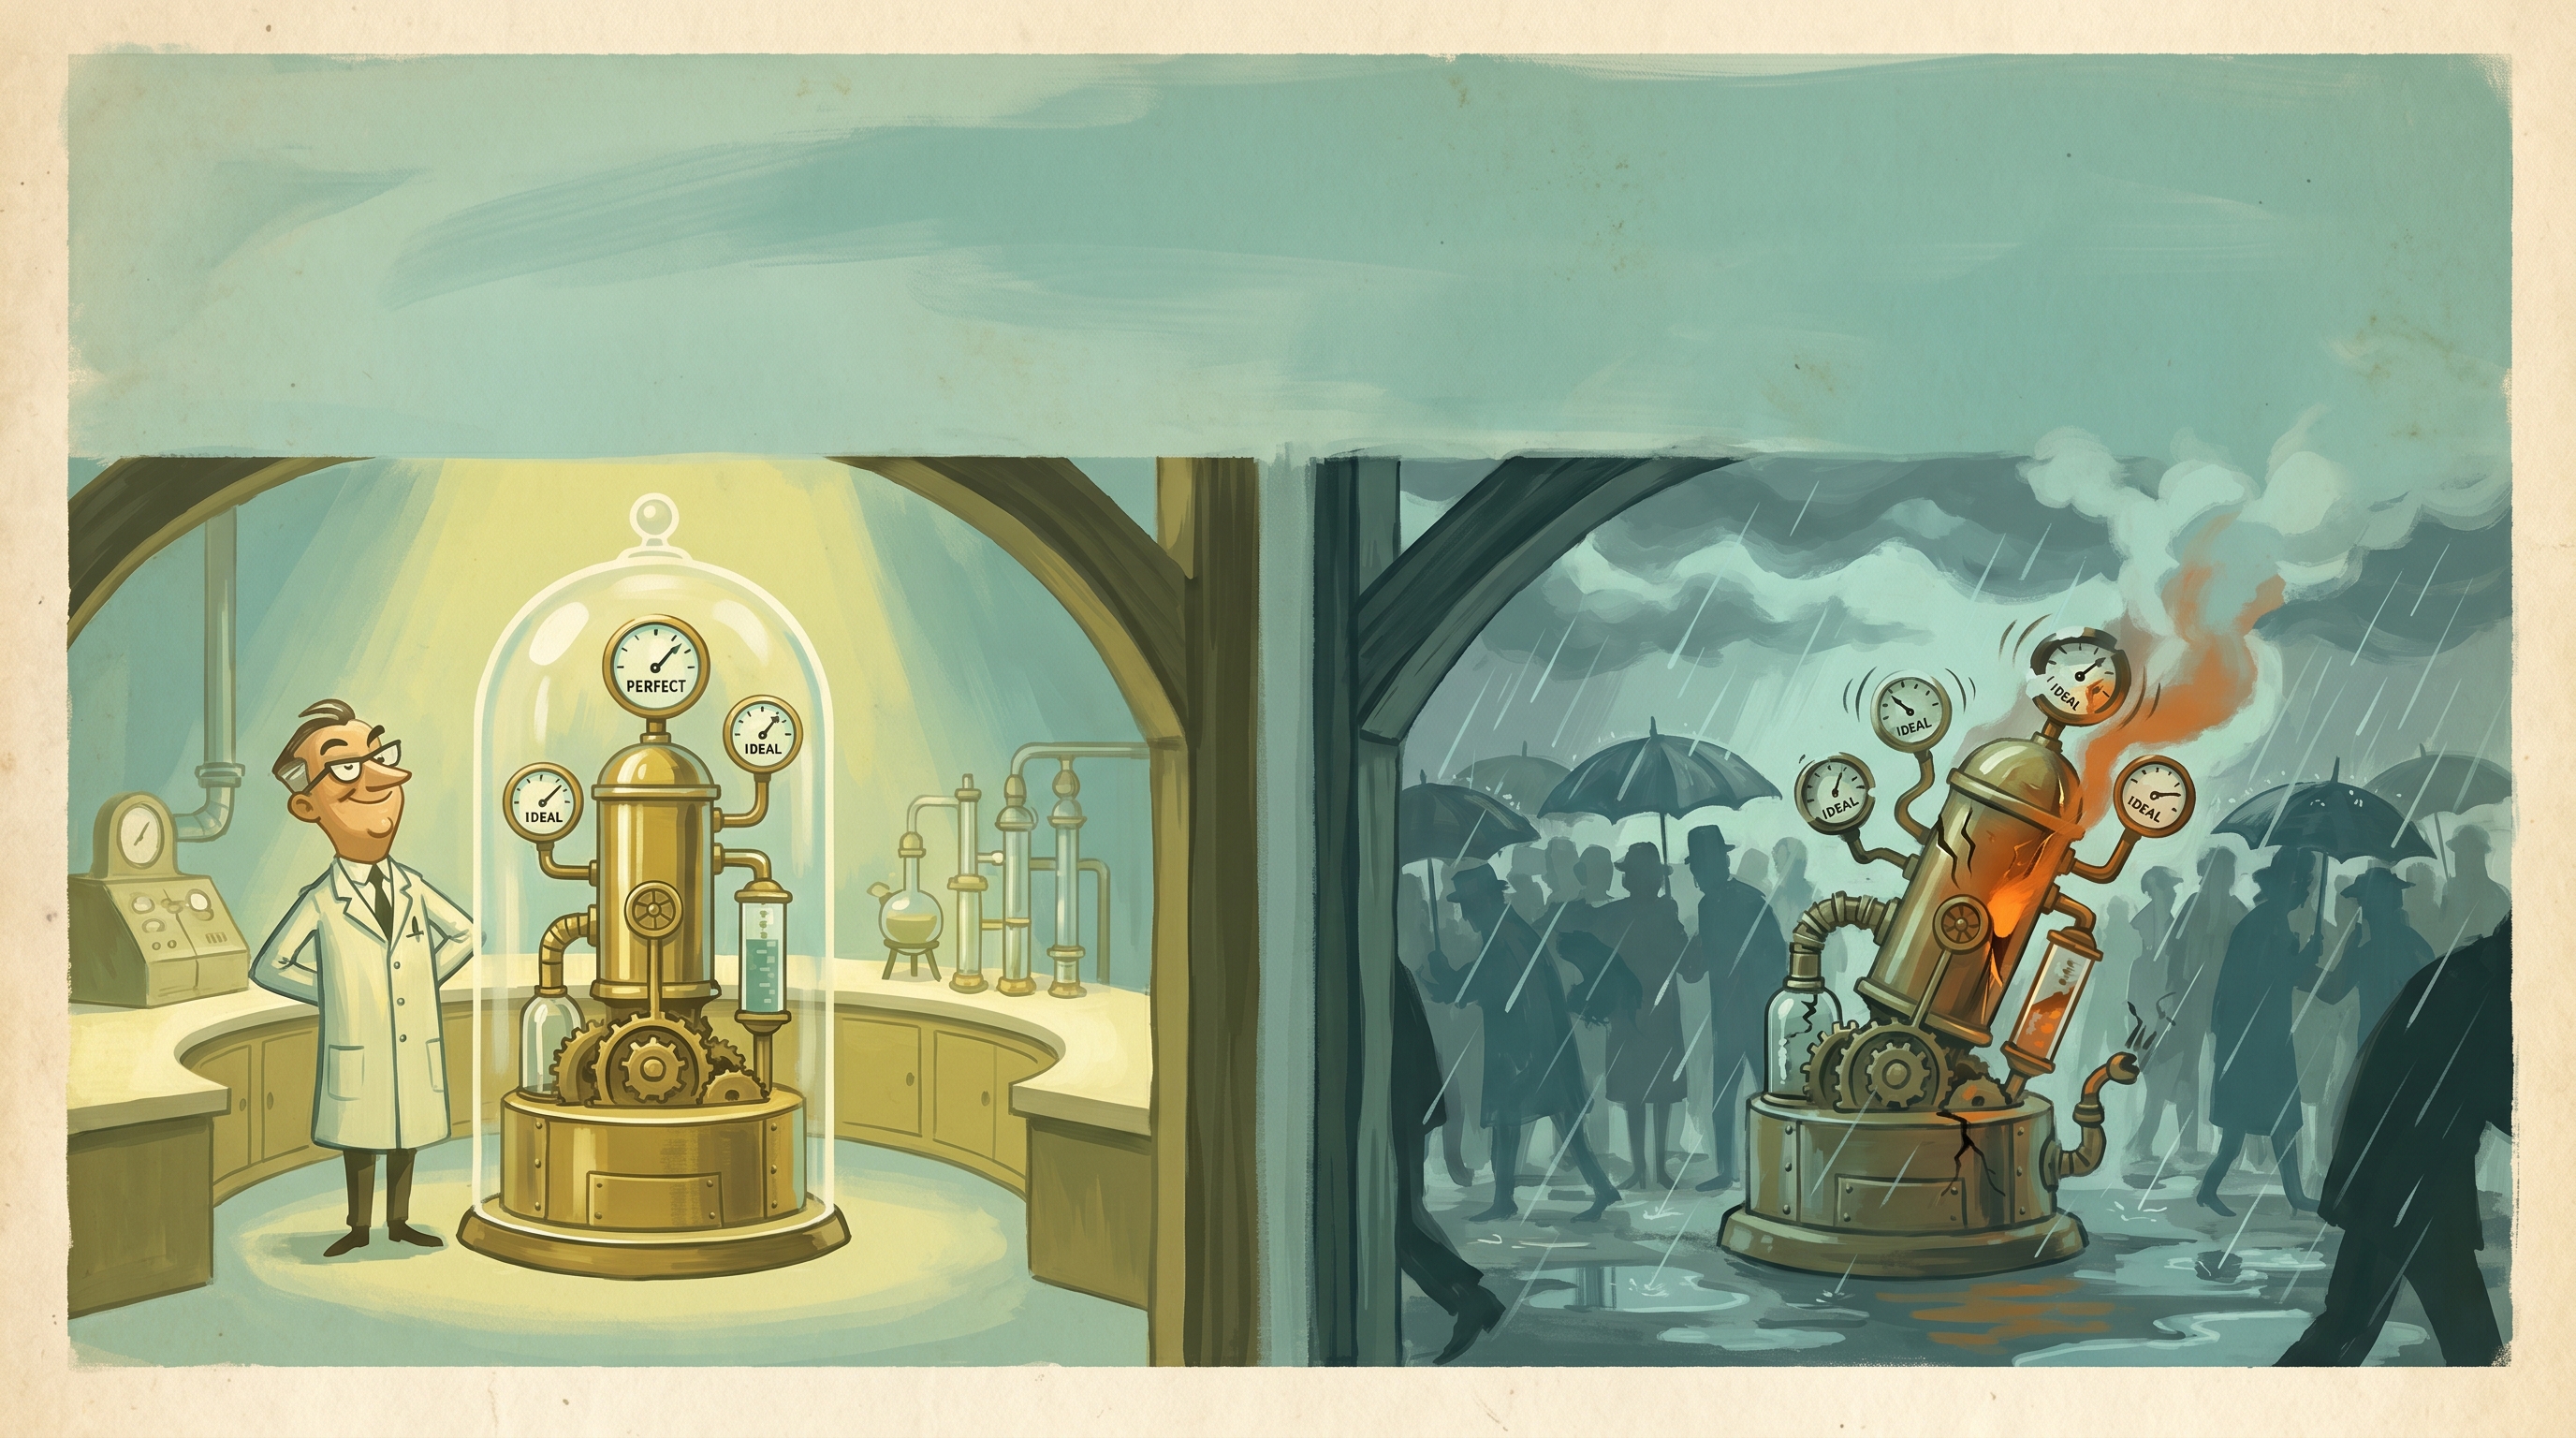
Every few months someone shows me a benchmark dashboard with numbers that would make a hardware vendor blush. P99 latency in the microseconds. Throughput that scales linearly. Beautiful flame graphs. Then the same system falls over in production at a tenth of the load.
Benchmarks aren't reality. They're a controlled fiction designed to make a specific component look good in isolation. That's useful for procurement and capacity planning. It's a terrible basis for prioritising engineering effort.
Here's the pattern I see repeatedly. A team spends six weeks shaving 200µs off a hot path. The benchmark improves by 40%. Production latency doesn't move. Why? Because the hot path was never the bottleneck. The bottleneck was a noisy neighbour on the shared database, a misconfigured connection pool, or a retry storm triggered by a flaky downstream that nobody owns.
Synthetic workloads have three lies baked in:
- Uniform load. Real traffic is bursty, correlated, and arrives at the worst possible moment. Your perfectly tuned cache hit ratio of 95% in the lab becomes 60% during a Black Friday spike because the working set explodes.
- Clean dependencies. Your benchmark talks to a local Postgres with no contention. Production talks to a Postgres that's also serving analytics queries someone wrote in 2019.
- No failure modes. Lab tests rarely include partial outages, slow DNS, certificate renewals, or the GC pause that lines up with a leader election.
The fix isn't to stop benchmarking. It's to stop treating benchmarks as a priority signal. Priority comes from production telemetry — SLO burn rate, error budget consumption, the actual P99 your users experience. If those numbers are healthy, your shiny benchmark improvement is engineering theatre. Worse, it's opportunity cost. Every week tuning a microbenchmark is a week not spent on the dependency graph, the retry semantics, or the runbook nobody's tested in eighteen months.
Performance work that doesn't trace back to a user-visible symptom or a measured SLO miss is a hobby. Treat it as such. Do it on Fridays if you must, but don't let it set the roadmap.
The lab will always be faster than production. That's the lab's job. It's not yours.