Not Everything Needs to Be Real-Time
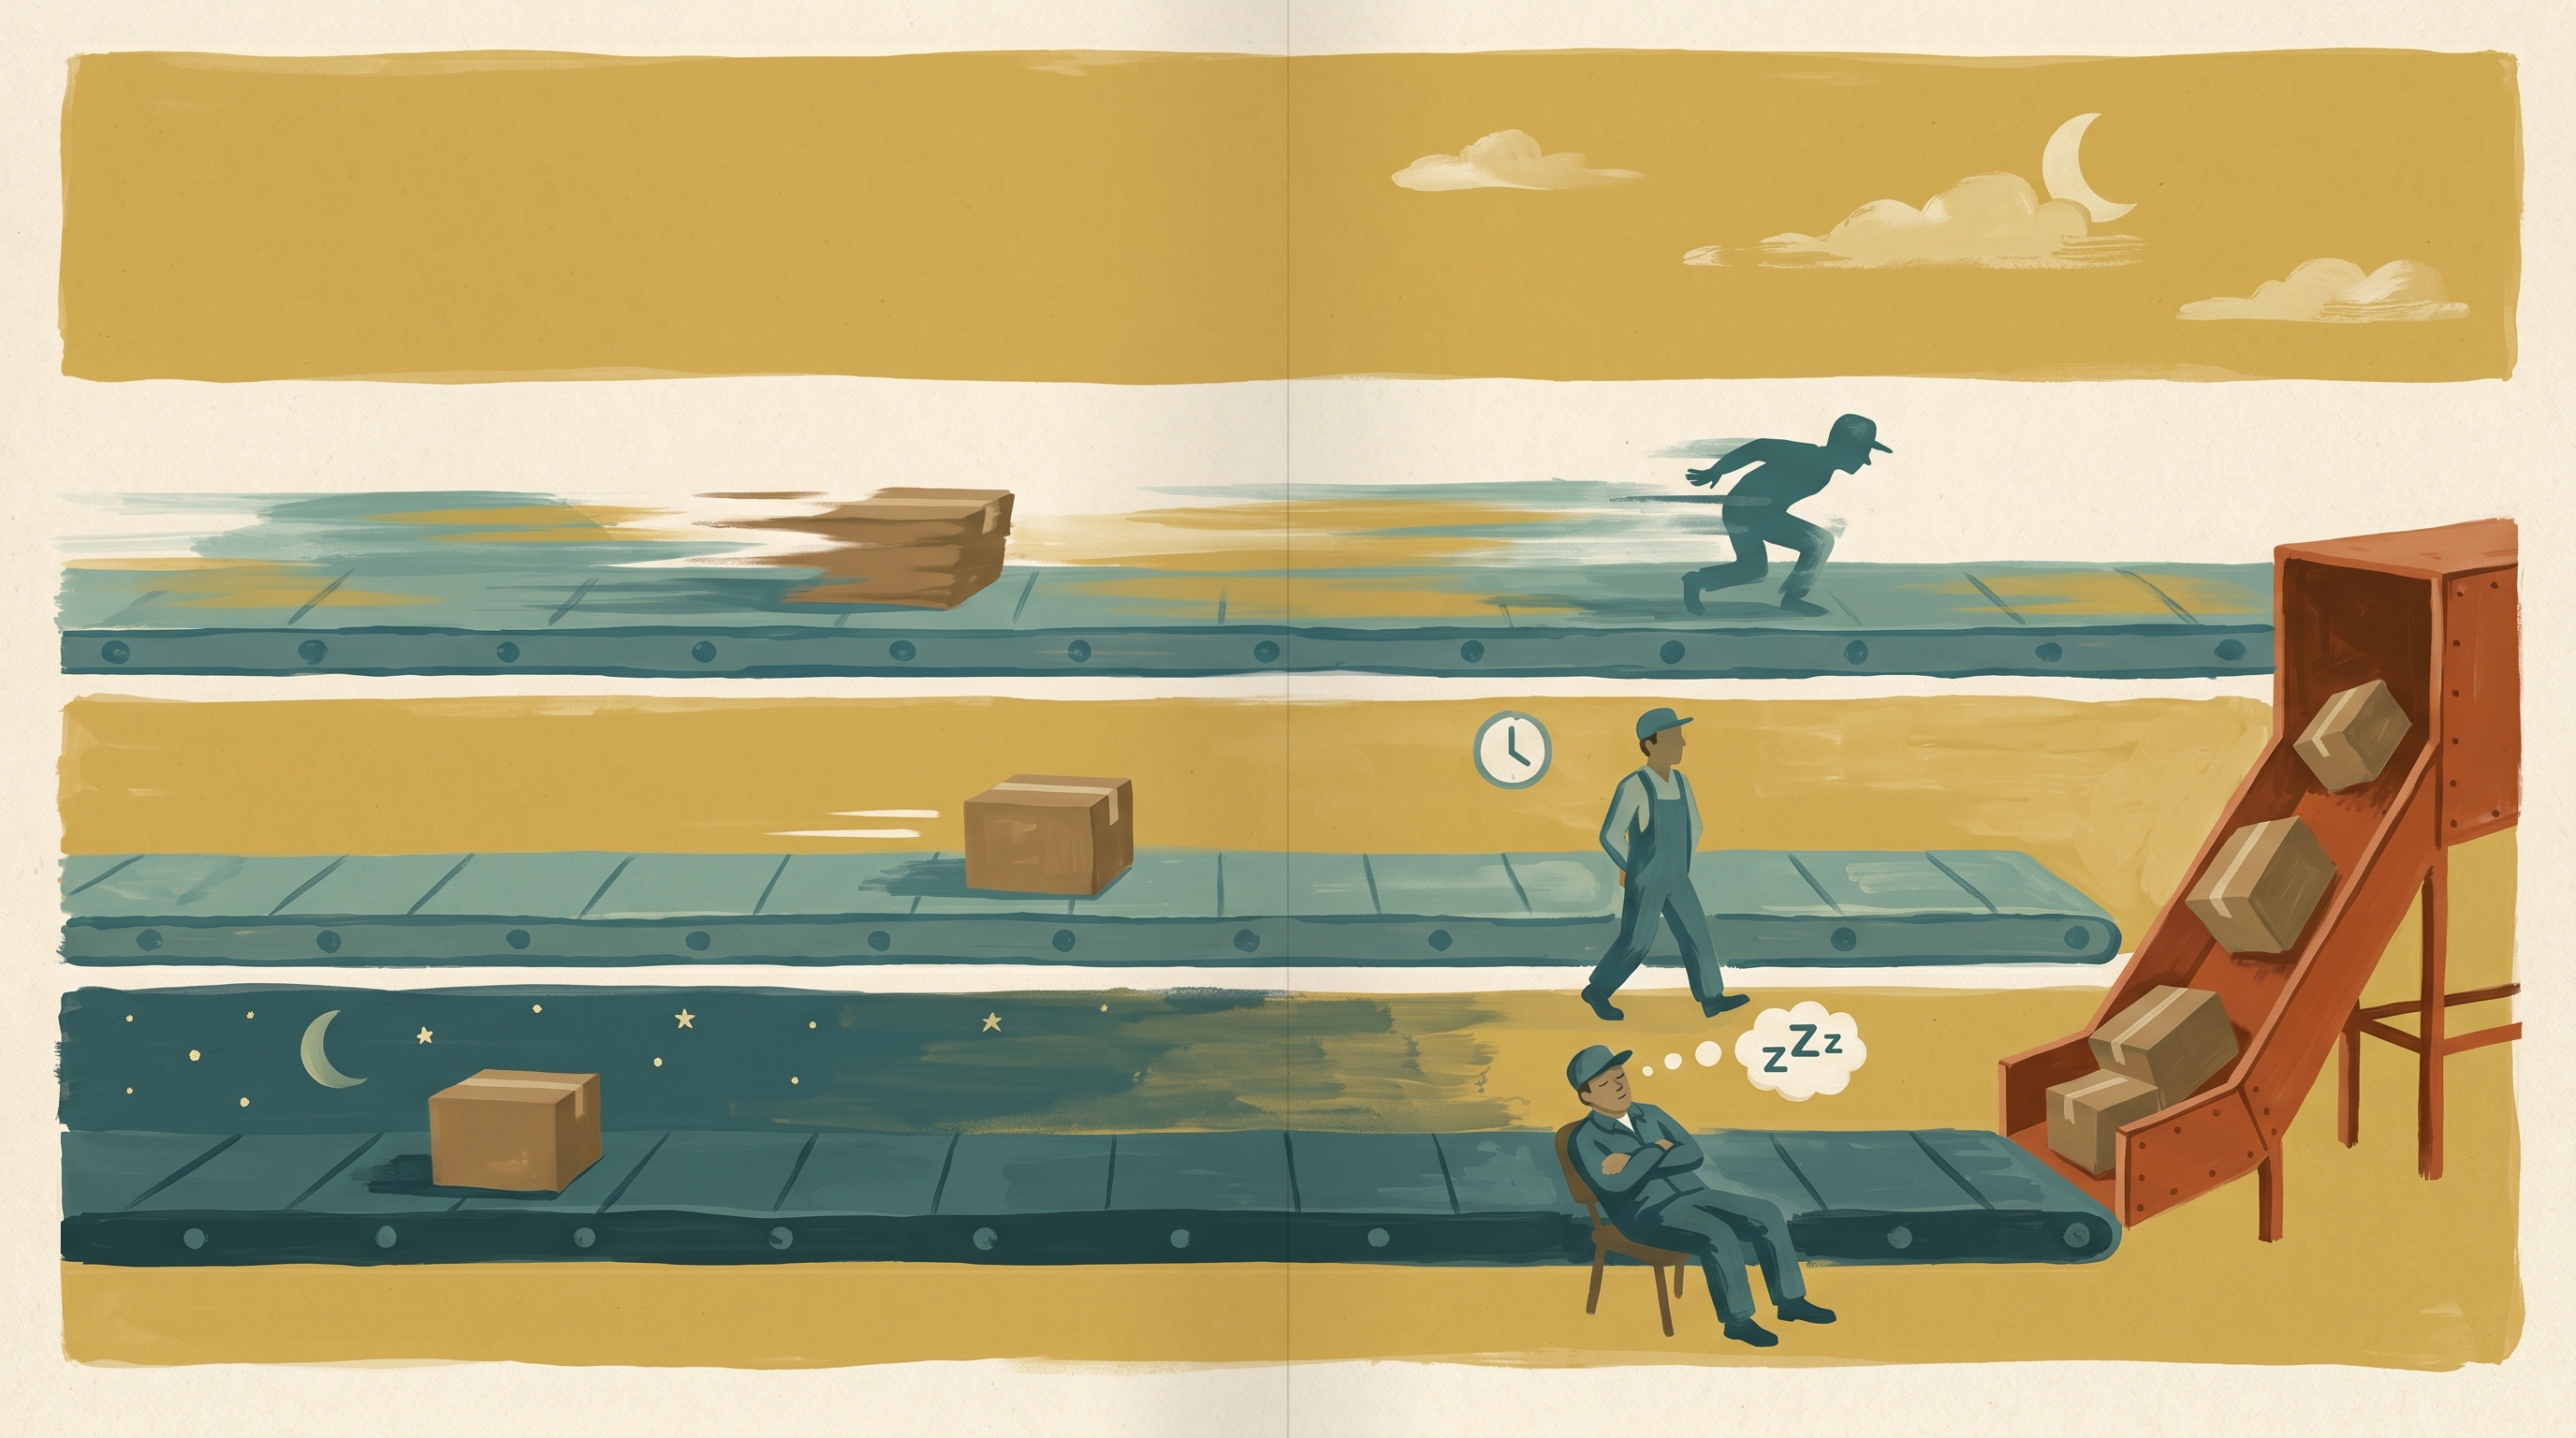
There's a pattern I've noticed in system design conversations where someone insists a feature needs to be real-time, and when you ask why, the answer is essentially: because that's what modern systems do. Not because the user will notice a five-second delay. Not because the business logic depends on immediacy. Just because building anything with perceptible latency feels like admitting defeat.
This is worth examining, because the cost difference between real-time and near-real-time is often substantial, and the difference between near-real-time and batch is more substantial still — and most of the time, the user cannot tell.
Real-time, near-real-time, and batch are not points on a spectrum of ambition. They're different architectural categories with different cost structures, failure modes, and operational footprints. Real-time means the system is committed to processing and responding within a latency bound that the user will directly perceive — sub-second, typically. Near-real-time means seconds to low minutes; the system feels responsive but isn't doing anything heroic. Batch means minutes to hours; the result appears later, possibly much later, and that's fine.
The costs scale accordingly. A real-time system needs low-latency infrastructure end to end: fast storage, minimal queueing, aggressive caching, careful connection pooling. You pay for that in compute, in database provisioning, in the operational complexity of keeping p99 latency bounded when traffic spikes. A near-real-time system can absorb bursts through a message queue, smooth out spikes, run smaller instances, and tolerate the occasional slow path without the user noticing. A batch system can run on whatever's left over at 2 AM.
The mistake is not that engineers build real-time systems. The mistake is that they build real-time systems without ever deciding that real-time was actually the requirement.
User perception is the thing to interrogate here, and it's frequently misread. Users are sensitive to latency in interactive flows — form submission, search, navigation. They are largely indifferent to latency in asynchronous ones. If you click "export to CSV" and a spinner appears, most users will accept a 15-second wait without complaint. If the same export took 15 seconds to return over a synchronous HTTP call, you'd get bug reports. The interaction model matters as much as the actual delay, and often more.
The same principle extends further than you'd expect. A reporting dashboard that refreshes every five minutes is not noticeably worse than one that streams live data, provided users understand that's what they're looking at. An email digest of activity that would otherwise require a real-time notification feed serves the same informational need at a fraction of the infrastructure cost. The question isn't "how fast?" but "fast relative to what?"
I've built systems where the entire event-processing pipeline was near-real-time except for one component that the business had decided, without much analysis, needed to be instant. That component ran on provisioned capacity three times the size of everything else combined, required the most operational care, and drove the most incidents. When we eventually timed how long users actually waited before acting on that data, it was never less than thirty seconds. We moved it to a queue-backed worker. Nobody noticed.
The architectural simplification that comes from relaxing latency constraints is underrated. Synchronous request-response chains are harder to scale, harder to retry, and harder to reason about under failure than asynchronous ones. A system that accepts work into a queue and processes it shortly afterwards can shed load gracefully, retry failed items without user-visible errors, and scale the processing layer independently of the ingestion layer. It can also fail components in isolation without taking down the user-facing surface.
None of that is free — you're trading latency headroom for engineering effort in a different dimension, and async systems have their own failure modes that synchronous ones don't. But the trade is often worth making, and it's certainly worth evaluating explicitly rather than defaulting to synchronous because that's the shape of the first implementation that came to mind.
The useful design exercise is to work backwards from what the user is actually trying to do. What decision do they make with this data? How fast does that decision need to happen? What's the consequence of being thirty seconds late? If there's no good answer to the last question, that's the system telling you something.
Latency is a product decision. Treating it as an engineering default — real-time because that's what serious systems do — is how you end up with a message broker running on the same provisioning tier as your core transaction database, serving a feature that sends a weekly digest.
Design for acceptable delay. It's almost always cheaper, usually simpler, and occasionally the thing that stops the pager going off at 3 AM.